All
Articles 181,632Blog Posts 166,033Tech Tutorials 48,651Research Papers 35,704News 22,611
⚡ AI Lessons

Dev.to · Shrijith Venkatramana
🎮 Reinforcement Learning
3w ago
Reward Hacking in LLMs: When the Model Learns to Win the Game Instead of Doing the Job
Hello, I'm Shrijith Venkatramana, and I'm building LiveReview — a blast-radius aware AI code review...

Dev.to · Marvin Okafor
🎮 Reinforcement Learning
⚡ AI Lesson
1mo ago
Building Deterministic RL Environments for Cloud Infrastructure Evaluation: What Actually Transfers From Production Engineering
AI models are increasingly being asked to design, deploy, secure, and recover production-grade...

Dev.to · Orkas
🎮 Reinforcement Learning
⚡ AI Lesson
1mo ago
Why RL Training Collapses on Long-Horizon Agents
Been heads-down lately, but I finally had a couple of days to catch up on some recent papers. Sharing...

Dev.to · Madhumitha Kolkar
🎮 Reinforcement Learning
⚡ AI Lesson
1mo ago
I Taught an Agent to Act Directly - No Q-Values Needed (Day 6: REINFORCE)
SERIES: Learning RL and JAX in Public - from zero to DeepMind :) Days 4 and 5 were value-based...

Dev.to · Paperium
🎮 Reinforcement Learning
2mo ago
Unified Multimodal Chain-of-Thought Reward Model through ReinforcementFine-Tuning

Dev.to · Sebastian Buzdugan
🎮 Reinforcement Learning
⚡ AI Lesson
2mo ago
Snapshot Once, Rollout a Thousand Times: A Practical RL Setup for Coding Agents
Your GPUs aren't the RL bottleneck, rebuilding the environment is. Snapshot the world once, fork it into thousands of rollouts. Real numbers, runnable harness.

Dev.to · VelocityAI
🎮 Reinforcement Learning
2mo ago
The Mechanical Turk of Modern AI: How Reinforcement Learning from Human Feedback (RLHF) Actually Works
You type a prompt into ChatGPT. It responds with a thoughtful, measured, and remarkably polite...

Dev.to · Devanshu Biswas
🎮 Reinforcement Learning
⚡ AI Lesson
2mo ago
Q-Learning From Scratch: Reinforcement Learning in a Gridworld
No labels, no "correct answer" — just rewards. Reinforcement learning lets an agent figure out the...

Dev.to · Shrijith Venkatramana
🎮 Reinforcement Learning
⚡ AI Lesson
2mo ago
Reinforcement Learning with Verifiable Rewards: Why AI is Learning to Grade Its Own Homework
Hello, I'm Shrijith Venkatramana. I'm building git-lrc, an AI code reviewer that runs on every...

Dev.to · keeper
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
The Missing Piece in Jason Wei's Framework: When to Go On-Policy
The Missing Piece in Jason Wei's Framework: When to Go On-Policy Jason Wei — the...

Dev.to · Garrin Costa, Jr.
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
On Optimization Objectives in Reinforcement Learning
Reinforcement Learning: Optimization and Objective Methods There are a few paradigms or...

Import AI
🎮 Reinforcement Learning
3mo ago
Import AI 460: Reward hacking society, RSI data from Anthropic; and RL-based quadcopter racing
When will markets price the singularity?
Latent Space
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
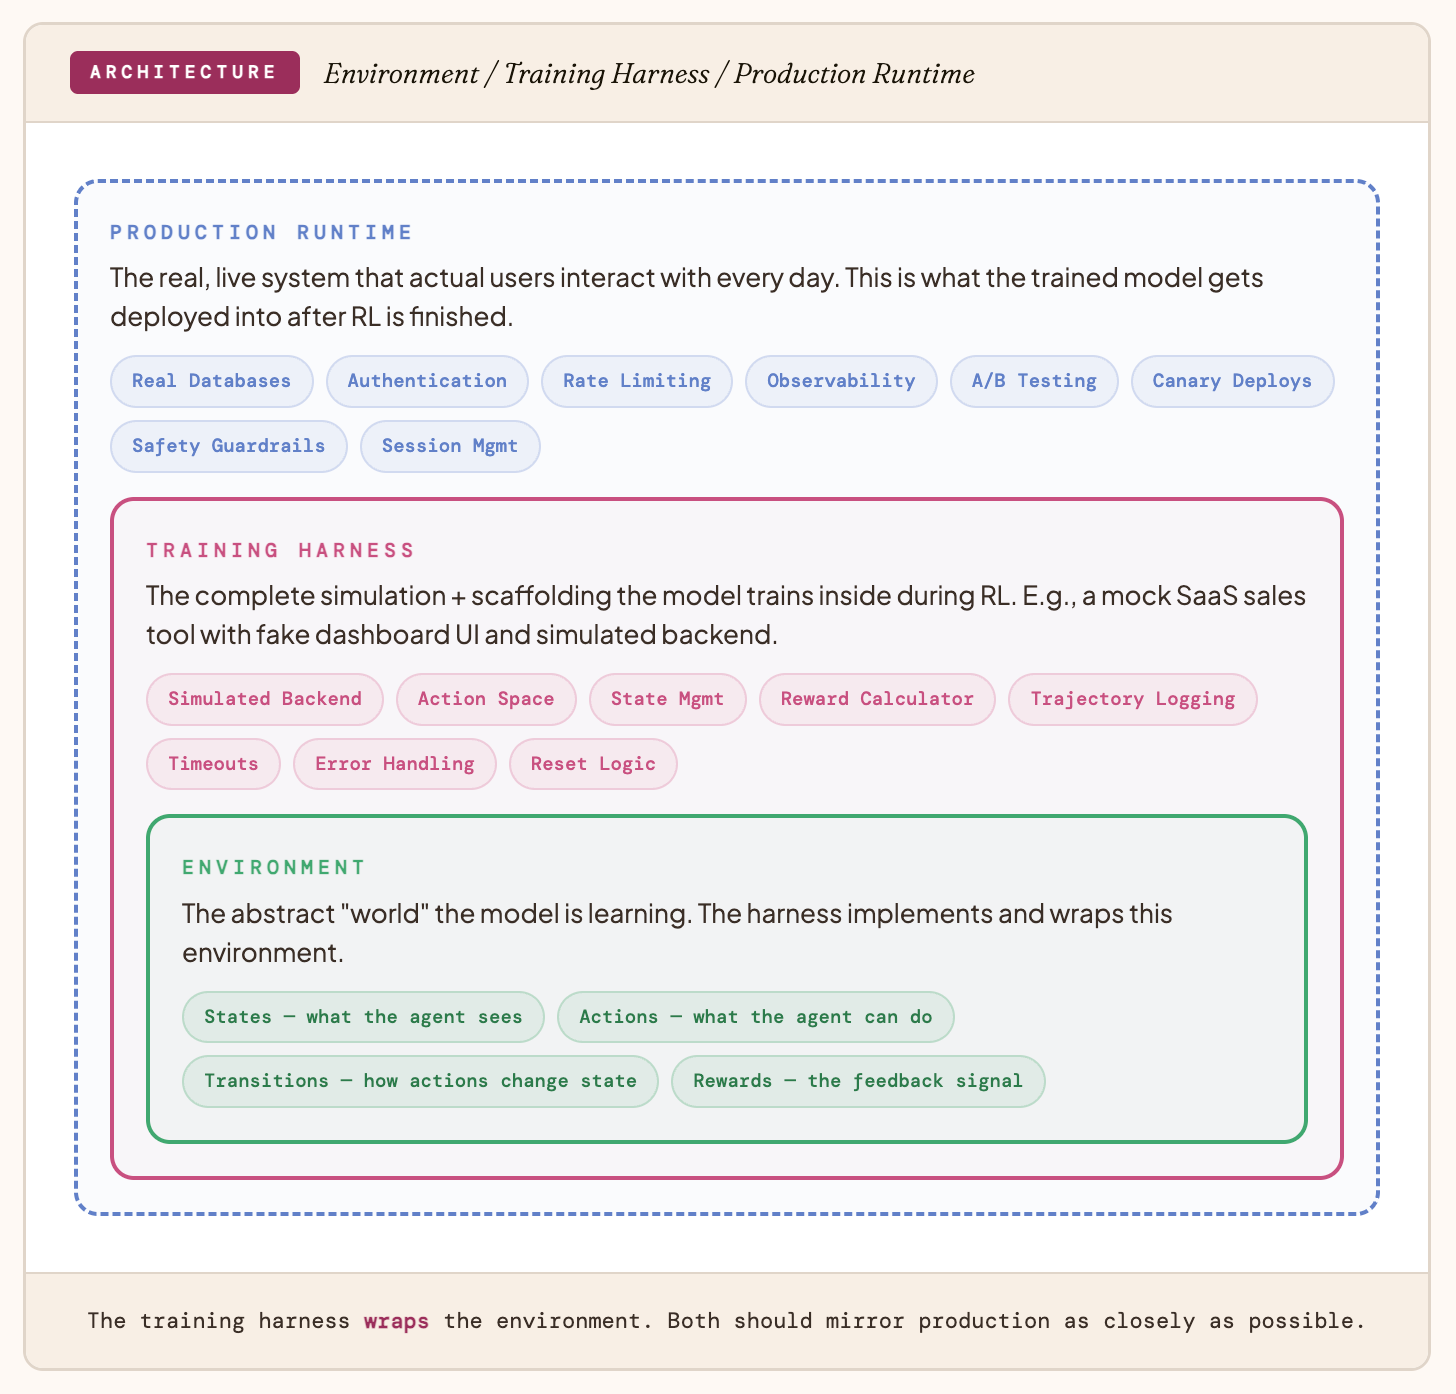
How to Stop Shipping Low-Quality RL Environments (with Examples)
Your broken harness is actively making the model worse. Here's what I keep seeing after years of eyeballing trajectories, and what you need to fix.

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
Understanding Reinforcement Learning with Human Feedback Part 6: How the Reward Model Trains the Original Model
In the previous article, we used loss functions and trained our reward model. In this article, we...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
Understanding Reinforcement Learning with Human Feedback Part 5: Training the Reward Model with Loss Functions
In the previous article, we created a reward model. In this article, we will continue exploring how...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
3mo ago
Understanding Reinforcement Learning with Human Feedback Part 4: Teaching Models Human Preferences
In the previous article, we explored the part where we collect human preferences. In this article, we...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Understanding Reinforcement Learning with Human Feedback Part 2: Aligning Pretrained Models
In the previous article, we explored the concept of pre-training and its limitations without a...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Understanding Reinforcement Learning with Neural Networks Part 6: Completing the Reinforcement Learning Process
In the previous article we covered the basics of training, and how rewards, derivatives and step-size...

Dev.to · saurabh naik
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
RLHF in 2026: when to pick PPO, DPO, or verifier-based RL
A working engineer's guide to InstructGPT-style RLHF — SFT, reward modeling, PPO with KL, DPO, and when RLVR replaces all of it.

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Understanding Reinforcement Learning with Neural Networks Part 5: Connecting Reward, Derivative, and Step Size
In the previous article, we explored the reward system in reinforcement learning In this article, we...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Understanding Reinforcement Learning with Neural Networks Part 4: Positive and Negative Rewards
In the previous article, we began the process of guessing the ideal output. Let us continue with the...

Dev.to · Rijul Rajesh
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Understanding Reinforcement Learning with Neural Networks Part 3: Guessing the Ideal Output
In the previous article, we explored the limitations of backpropagation and why it is not ideal when...

Dev.to · Stat Phantom
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Removing PER From Rainbow DQN Set a New Snake AI World Record
Greetings all! Quick context: this is part of an ongoing series where I'm building Rainbow DQN one...

Dev.to · Ethan
🎮 Reinforcement Learning
⚡ AI Lesson
4mo ago
Top 5 Reinforcement Learning Environments
An RL agent has nothing to learn from without an environment to act in. This piece covers what an RL...
 DeepCamp AI