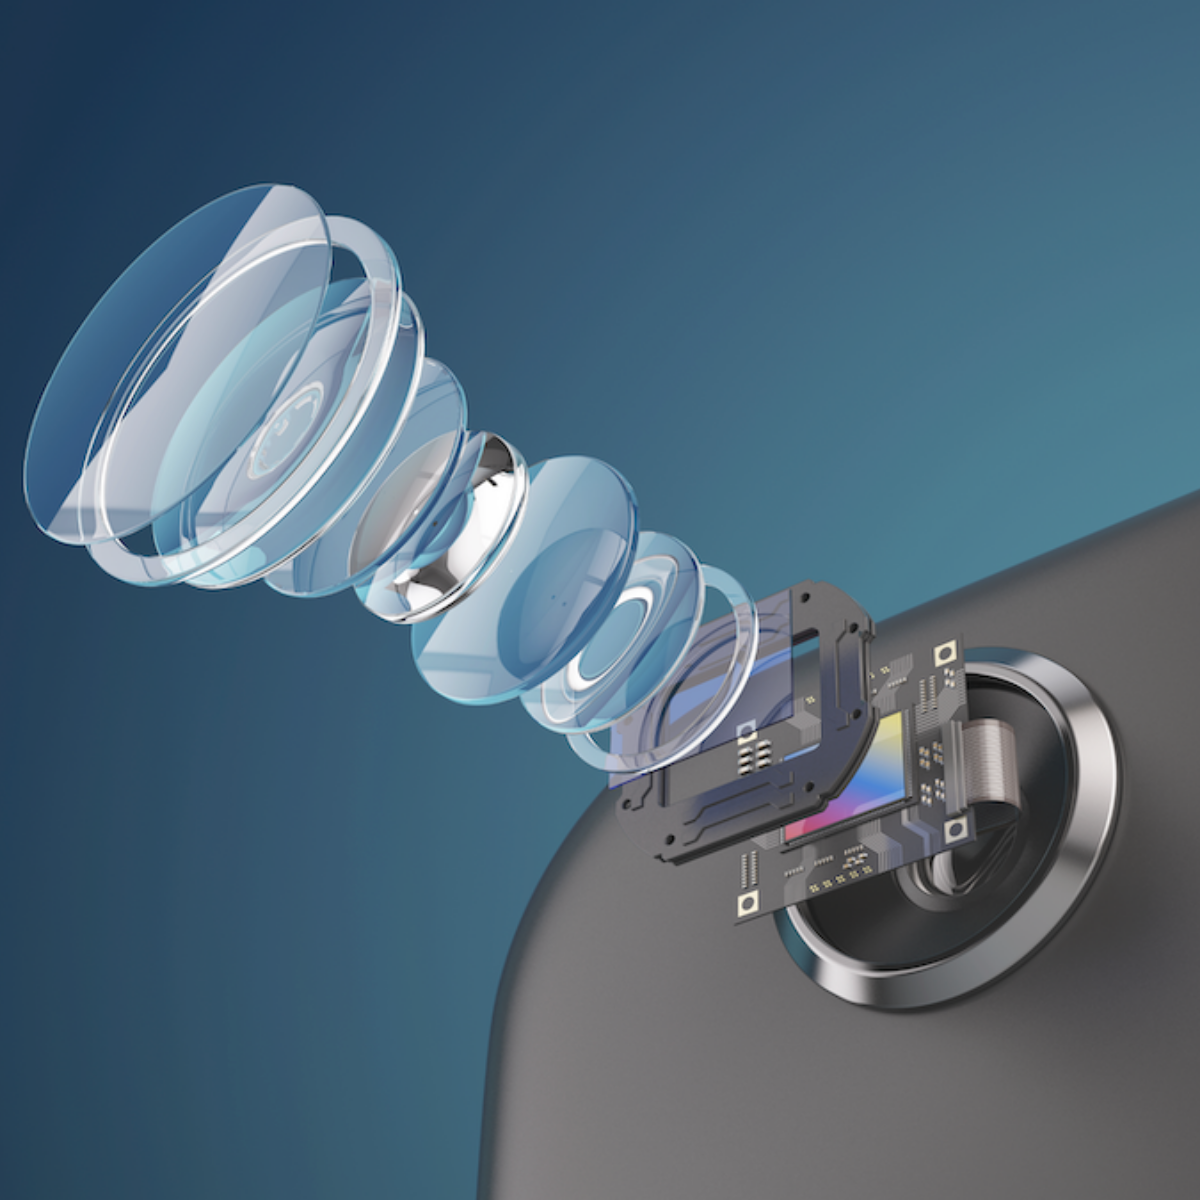
Camera and Imaging
Key Takeaways
Covers fundamentals of camera and imaging for computer vision systems
Original Description
This course covers the fundamentals of imaging – the creation of an image that is ready for consumption or processing by a human or a machine. Imaging has a long history, spanning several centuries. But the advances made in the last three decades have revolutionized the camera and dramatically improved the robustness and accuracy of computer vision systems. We describe the fundamentals of imaging, as well as recent innovations in imaging that have had a profound impact on computer vision.
This course starts with examining how an image is formed using a lens camera. We explore the optical characteristics of a camera such as its magnification, F-number, depth of field and field of view. Next, we describe how solid-state image sensors (CCD and CMOS) record images, and the key properties of an image sensor such as its resolution, noise characteristics and dynamic range. We describe how image sensors can be used to sense color as well as capture images with high dynamic range. In certain structured environments, an image can be thresholded to produce a binary image from which various geometric properties of objects can be computed and used for recognizing and locating objects. Finally, we present the fundamentals of image processing – the development of computational tools to process a captured image to make it cleaner (denoising, deblurring, etc.) and easier for computer vision systems to analyze (linear and non-linear image filtering methods).
AI explanation not available for this lesson yet
This lesson is still being prepared for the AI tutor. In the meantime, explore lessons that are ready.
Browse explainer-ready lessons →
Related Reads
📰
📰
📰
📰
Open‑vocab relation predictor triples recall
Dev.to · Papers Mache
Bounding Box Annotation at Scale: Why Object Density Matters More Than Image Count
Dev.to · Naanhe Gujral
How Zalgo Glitch Text Works Behind the Scenes
Dev.to · Thushara He
How Tata Elxsi detects industrial safety risks in seconds on AWS
AWS Machine Learning
🎓
Tutor Explanation
 DeepCamp AI